-20%

Federated Multi-View Learning for Heterogeneous Edge Data

0 Orders 0 Wish listed

₹4,999.00

Qty
Total price:
  ₹4,999.00

Detail Description

1. Abstract

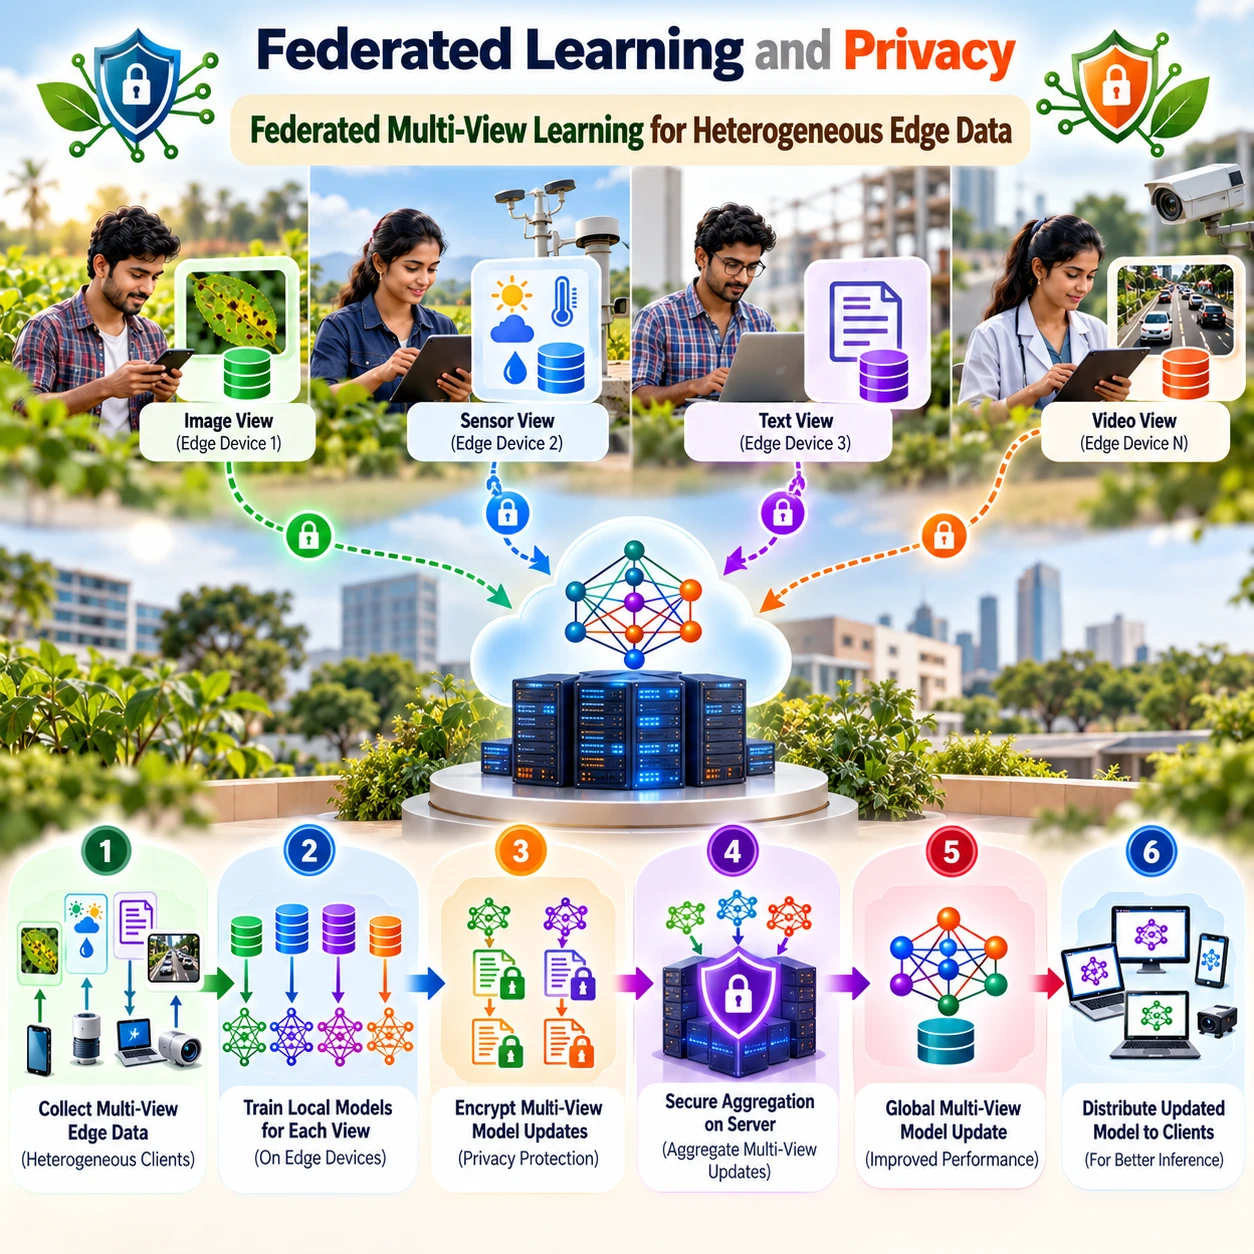
Federated Multi-View Learning for Heterogeneous Edge Data is a machine learning project that enables multiple edge devices to collaboratively learn from diverse data sources while keeping their raw data locally stored. Different edge devices may collect data in various forms, such as images, sensor readings, text, and numerical measurements. These differences create challenges for conventional machine learning models that rely on uniform data formats and centralized processing. The proposed system combines Federated Learning and Multi-View Learning to process multiple data representations across distributed clients. Each client extracts features from its available data views and trains a local model. The server aggregates compatible model updates to build a shared global model without directly collecting raw client data. The project aims to improve collaborative learning, support heterogeneous edge environments, and evaluate model performance across different data distributions and feature types.

2. Objectives

  1. To develop a federated multi-view learning framework for heterogeneous edge devices.
  2. To process different data views, such as sensor readings, images, and numerical features.
  3. To enable collaborative model training without directly sharing raw datasets.
  4. To simulate edge clients with different data distributions and feature availability.
  5. To combine compatible local model updates using federated aggregation.
  6. To improve learning performance across diverse edge data sources.
  7. To evaluate model performance using accuracy, precision, recall, and F1-score.
  8. To visualize client-level performance and global model convergence.

3. Existing System

Traditional machine learning systems generally collect data from different devices and process it centrally. Standard Federated Learning supports distributed training but often assumes that clients use compatible model architectures and feature representations. When edge devices have different data types, feature spaces, or available views, combining their knowledge becomes challenging.

Disadvantages

  1. Difficulty processing multiple data views.
  2. Limited compatibility between heterogeneous client datasets.
  3. Increased privacy risks in centralized data processing.
  4. Reduced model performance when data distributions differ.
  5. Challenges integrating different feature representations.
  6. Limited adaptability to edge devices with different data capabilities.

4. Proposed System

The proposed system combines Federated Learning with Multi-View Learning to support collaborative training across heterogeneous edge devices. Each client processes its available data views, extracts meaningful features, and trains a local model. Compatible model updates or shared representations are transmitted to a central server for aggregation.

The server combines compatible updates using an appropriate federated aggregation algorithm, such as Federated Averaging (FedAvg), and distributes the global model to participating clients. The framework can use view-specific feature extractors and a shared representation layer to support different data sources.

Key Features

  1. Federated learning across multiple edge clients.
  2. Multi-view feature extraction and representation learning.
  3. Support for heterogeneous data distributions.
  4. Local data processing and privacy-aware collaboration.
  5. Global model aggregation.
  6. Client-level performance evaluation.
  7. Visualization of training progress and model accuracy.
  8. Dashboard for monitoring federated learning experiments.

5. Implementation Procedure

1. Dataset Collection: Select a suitable multi-view dataset or combine compatible public datasets representing different data views, such as sensor measurements, numerical features, or images.

2. Data Preprocessing: Clean the data, handle missing values, normalize numerical features, and prepare each view for model training.

3. Edge Client Simulation: Divide the data into multiple clients representing different edge devices or organizations.

4. Multi-View Configuration: Define the available data views for each client and identify the shared prediction task or compatible labels.

5. Feature Extraction: Use suitable feature extraction methods or neural network encoders to transform each data view into a useful representation.

6. Local Model Development: Build local models that combine view-specific features with shared representations for prediction.

7. Federated Learning Setup: Use Flower to coordinate local training and communication between clients and the central server.

8. Model Aggregation: Apply FedAvg or another compatible aggregation strategy to combine updates from participating clients.

9. Iterative Training: Distribute the global model and repeat local training and aggregation over multiple communication rounds.

10. Performance Evaluation: Measure accuracy, precision, recall, F1-score, training time, and client-level performance.

11. Dashboard Development: Build a Streamlit or Flask interface to display training metrics, client data views, and model performance.

12. Testing: Compare the federated multi-view approach with local-only and suitable baseline models under different client distributions and view availability settings.

6. Software Requirements

ComponentTechnology
Programming LanguagePython
Development EnvironmentVS Code / Jupyter Notebook
Machine LearningScikit-learn
Federated LearningFlower
Deep LearningPyTorch / TensorFlow
Data ProcessingPandas, NumPy
Image Processing (Optional)OpenCV, Pillow
VisualizationMatplotlib, Seaborn
Web FrameworkStreamlit / Flask
Dataset FormatCSV / Images / Sensor Data
Operating SystemWindows / Linux

7. Hardware Requirements

ComponentMinimum Requirements
ProcessorIntel Core i3 or equivalent
RAM8 GB
Storage10 GB free space
NetworkInternet or local network
Edge DevicesSimulated clients or physical devices
Operating SystemWindows 10/11 or Linux
GPUOptional

Recommended: Intel Core i5 or equivalent, 16 GB RAM, and SSD storage for smoother experiments involving multiple clients and deep learning models.

8. Advantages of the Project

  1. Privacy-Aware Learning: Raw client data can remain on individual devices.
  2. Multi-View Integration: Combines information from different data representations.
  3. Heterogeneous Data Support: Enables experiments with clients that have different data distributions or available views.
  4. Collaborative Training: Multiple clients contribute to a shared prediction model.
  5. Reduced Centralized Data Storage: Avoids routinely transferring complete datasets to a central server.
  6. Scalability: Supports additional clients and data sources.
  7. Flexible Architecture: Can be adapted to IoT, healthcare, smart cities, and edge analytics.
  8. Performance Monitoring: Enables comparison of model accuracy and convergence across clients.


No review given yet!

Fast Delivery all across the country
Safe Payment
7 Days Return Policy
100% Authentic Products

You may also like

View all

Explainable Decision-Making for Autonomous Vehicles

₹4,999.00

Sensor-Fusion-Based Autonomous Navigation

₹4,999.00

Cooperative Perception for Connected Vehicles

₹4,999.00

Digital Twin for Autonomous Vehicle Networks

₹4,998.99

Reinforcement Learning-Based Traffic Signal Control

₹4,999.00

Federated Multi-View Learning for Heterogeneous Edge Data
₹4,999.00 ₹0.00
₹4,999.00
4999