-20%

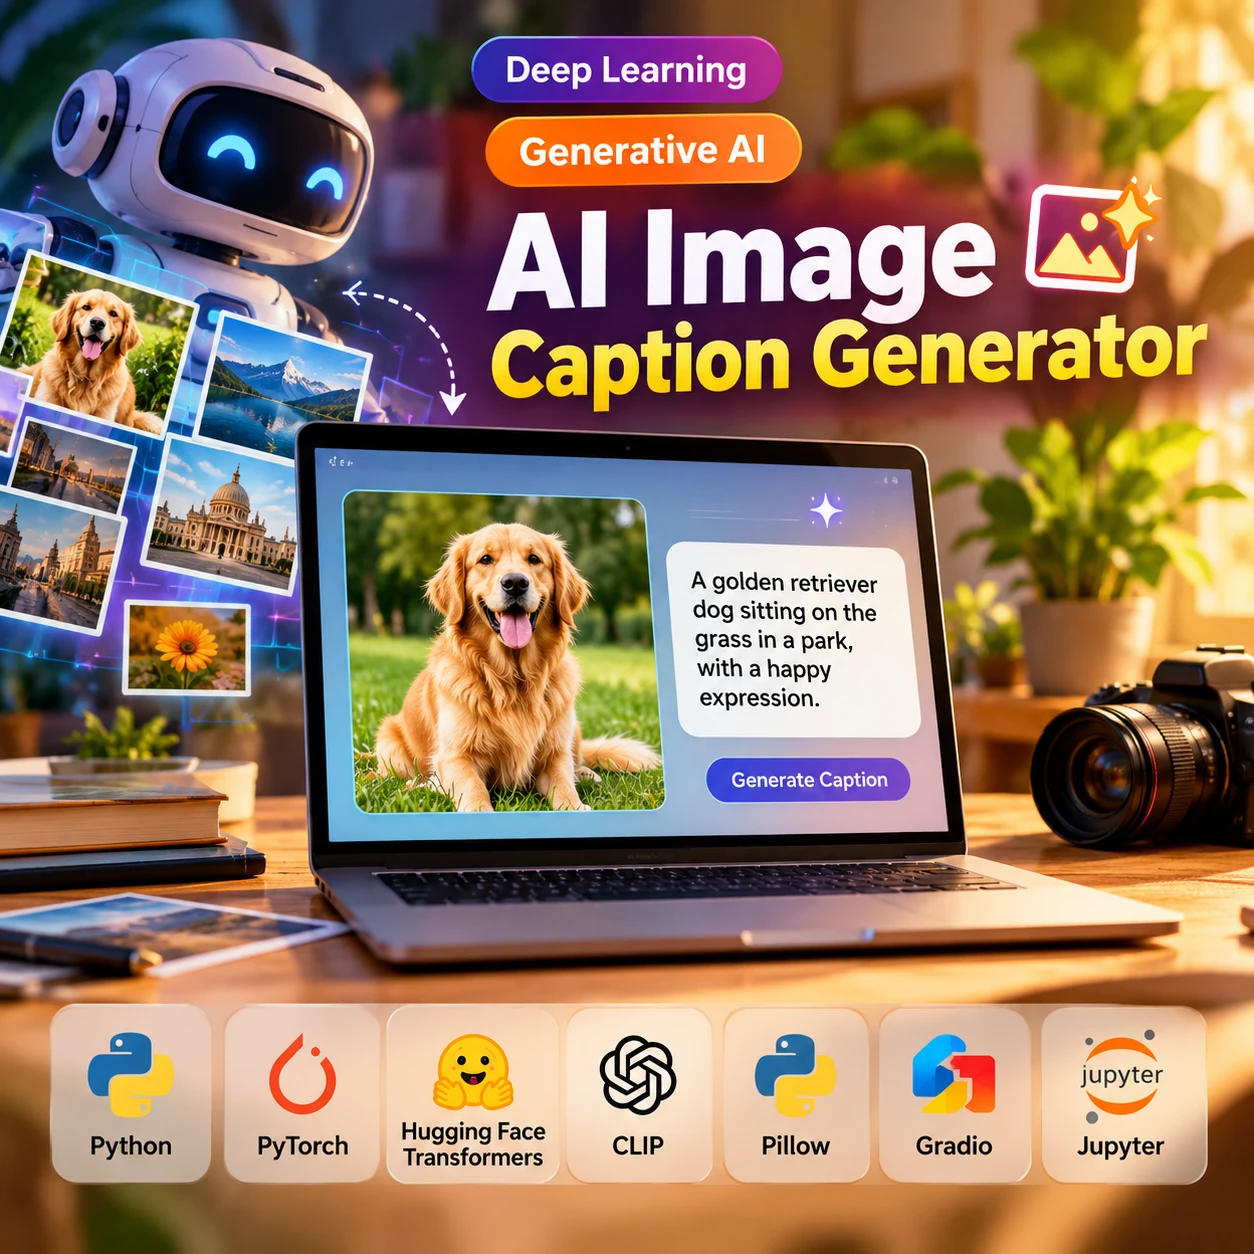
AI Image Caption Generator

0 Orders 0 Wish listed

₹4,999.00

Qty
Total price:
  ₹4,999.00

Detail Description


1. Abstract

The AI Image Caption Generator is an artificial intelligence project that automatically generates meaningful and natural-language descriptions for uploaded images. The system combines computer vision, deep learning, Natural Language Processing (NLP), and Generative AI techniques to understand the visual content of an image and produce a relevant caption. The image is first processed using a vision model to extract important visual features such as objects, people, scenes, and activities. These features are then passed to a language-generation component that creates a grammatically meaningful caption. The system can be useful for image accessibility, content management, social media, digital libraries, and AI-based image understanding.

2. Objectives

  1. To automatically generate captions for uploaded images.
  2. To analyze and understand the visual content of images using AI.
  3. To identify important objects, people, scenes, and activities present in an image.
  4. To apply deep learning and computer vision techniques for image feature extraction.
  5. To generate natural-language descriptions using NLP or generative AI models.
  6. To reduce the need for manual image description.
  7. To support accessibility for visually impaired users.
  8. To provide a simple interface for uploading images and viewing generated captions.
  9. To improve image search and content organization through automatically generated descriptions.
  10. To demonstrate the practical application of multimodal and Generative AI technologies.

3. Existing System

In traditional systems, image descriptions are generally created manually by users, content creators, photographers, or data-entry personnel. Some basic image-processing applications can identify objects or classify images, but they may not generate complete and meaningful natural-language descriptions.

Limitations of the Existing System

  1. Manual caption creation requires significant time and effort.
  2. Descriptions may vary depending on the person creating them.
  3. Large collections of images are difficult to annotate manually.
  4. Basic image classification systems provide labels rather than complete descriptions.
  5. Human annotation can be expensive for large datasets.
  6. Manual descriptions may miss important visual information.
  7. Limited scalability for real-time image caption generation.

4. Proposed System

The proposed AI Image Caption Generator automatically analyzes an image and generates a meaningful caption using AI.

The system follows the workflow:

Image Upload → Image Preprocessing → Visual Feature Extraction → Image Understanding → Caption Generation → Generated Caption

A pretrained vision model or CNN/Transformer-based vision encoder can extract visual features from the image. A language model or decoder then converts these features into a natural-language caption.

Possible technologies/models include:

  1. CNN-based image encoders
  2. Vision Transformers (ViT)
  3. CLIP-based vision-language models
  4. BLIP / BLIP-2
  5. Vision-Language Models (VLMs)
  6. LSTM-based caption decoders
  7. Transformer-based caption generators
  8. Generative AI / Large Multimodal Models

The generated caption can be displayed through a web interface where users upload an image and receive an AI-generated description.

5. Implementation Procedure

Step 1: Dataset Collection

Collect an image-caption dataset such as MS COCO, Flickr30k, or another suitable image-caption dataset.

Step 2: Image Preprocessing

  1. Resize images to the required dimensions.
  2. Normalize pixel values.
  3. Remove corrupted or unsuitable images.
  4. Apply image augmentation when required.

Step 3: Text Preprocessing

Process the reference captions by:

  1. Converting text to lowercase.
  2. Removing unnecessary characters.
  3. Tokenizing sentences.
  4. Creating vocabulary/token mappings.
  5. Adding start and end tokens where required.

Step 4: Visual Feature Extraction

Use a pretrained CNN, Vision Transformer, or vision-language model to extract meaningful features from the image.

Step 5: Caption Generation

Pass the extracted visual representation to an LSTM, Transformer, or Generative AI language model to generate a caption.

Step 6: Model Training/Fine-Tuning

Train or fine-tune the selected model using image-caption pairs when a custom model is required.

Step 7: Model Evaluation

Evaluate generated captions using appropriate metrics such as:

  1. BLEU
  2. ROUGE
  3. METEOR
  4. CIDEr
  5. SPICE

Human evaluation can also be used to assess caption relevance and readability.

Step 8: Application Development

Develop a user-friendly interface using Streamlit, Flask, FastAPI, or React.

Step 9: Image Prediction

The user uploads an image, and the trained/pretrained model analyzes it and generates a caption.

Step 10: Result Display

Display the uploaded image along with the generated caption and optionally provide options to copy, download, or regenerate the caption.

6. Software Requirements

RequirementTechnology
Programming LanguagePython
Development EnvironmentVS Code / Jupyter Notebook / Google Colab
Deep LearningPyTorch / TensorFlow
Computer VisionOpenCV / Pillow
AI ModelsCNN / ViT / BLIP / Vision-Language Models
NLPTransformers / NLTK / spaCy
Data ProcessingNumPy / Pandas
Machine LearningScikit-learn
Web InterfaceStreamlit / Flask / FastAPI / React
VisualizationMatplotlib / Plotly
DatasetMS COCO / Flickr30k / Custom Dataset
BrowserGoogle Chrome / Microsoft Edge
Operating SystemWindows / Linux / macOS

7. Hardware Requirements

  1. Processor: Intel Core i5 or equivalent
  2. RAM: Minimum 8 GB
  3. Recommended RAM: 16 GB
  4. Storage: Minimum 20 GB free space
  5. GPU: NVIDIA GPU with CUDA support recommended for deep learning/fine-tuning
  6. Display: 1366 × 768 resolution or higher
  7. Input: Keyboard and mouse
  8. Internet: Required for downloading datasets, pretrained models, and APIs
  9. Cloud Option: Google Colab or other GPU-enabled cloud platforms can be used for model training.

8. Advantages of the Project

  1. Automatically generates image descriptions.
  2. Reduces manual image-captioning effort.
  3. Provides fast and consistent captions.
  4. Supports accessibility and assistive technologies.
  5. Useful for large-scale image datasets.
  6. Combines computer vision and NLP.
  7. Can improve image search and content organization.
  8. Useful for social media and digital content management.
  9. Can be integrated into websites and mobile applications.
  10. Supports modern multimodal and Generative AI applications.
  11. Can be extended to multiple languages.
  12. Can be customized for specific domains such as healthcare, education, e-commerce, and surveillance.


No review given yet!

Fast Delivery all across the country
Safe Payment
7 Days Return Policy
100% Authentic Products

You may also like

View all

Blockchain-Based Model Ownership Verification

₹4,999.00

Decentralized Federated Learning

₹4,999.00

Cryptocurrency Fraud Detection

₹4,999.00

Smart Contract Vulnerability Detection using ML

₹4,999.00

Blockchain-Based E-Voting

₹4,999.00

AI Image Caption Generator
₹4,999.00 ₹0.00
₹4,999.00
4999